Short version
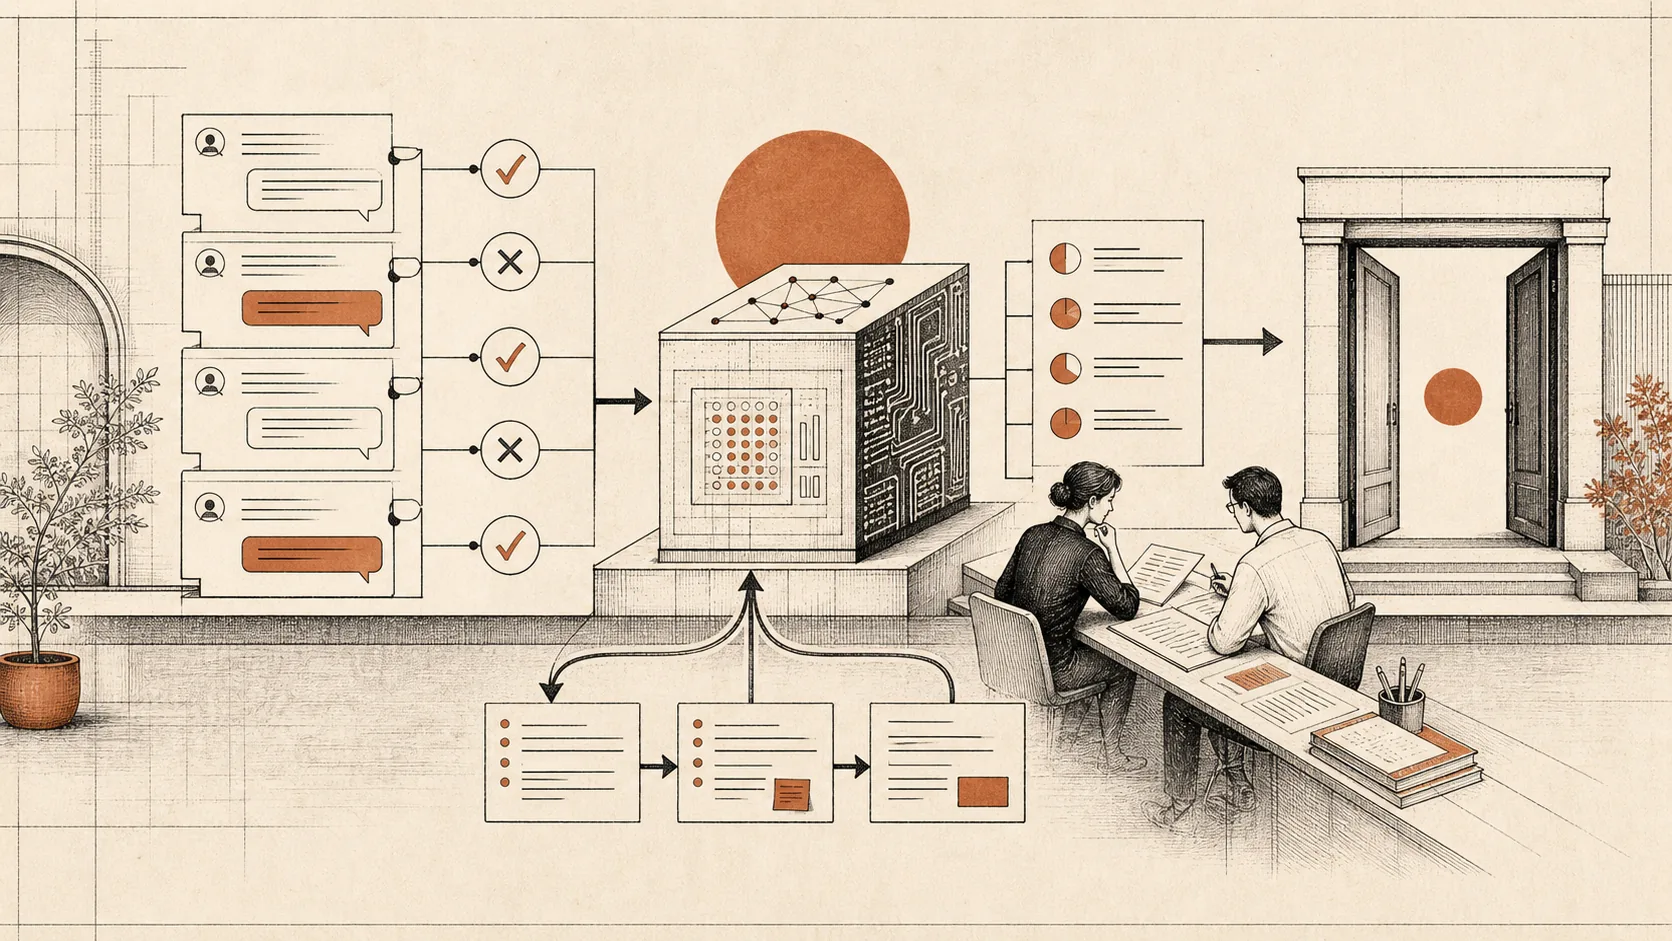
AI evals are repeatable quality checks for an AI system: a set of real scenarios you rerun after every prompt, model, or retrieval change to see whether things actually got better.
Normal software has tests. AI systems need tests too, but the shape is different. A model may answer in different words each time, so the useful question is not exact text equality. The useful question is behavior: did it find the right source, avoid invented facts, and hand risky cases to a person?
Evals start with manual review. Take real chats, answers, documents, support mistakes, and escalations. Mark where the agent lies, loses a task, answers too broadly, or forgets escalation. After 20-50 examples, the same few failure modes usually explain most of the damage. That is the moment to automate.
Then automate the checks. Some checks are code-based: valid JSON, answer length, source link present, refusal triggered. Others need LLM-as-judge: another model grades faithfulness, completeness, tone, or safety. That judge must be calibrated against human review, because it is also a model.
For RAG, test retrieval separately. If the system did not retrieve the right passage, the final answer is not the first suspect. If it retrieved the right passage and still invented something, inspect the prompt, model choice, and refusal instruction.
Evals matter before launch because they let you improve the agent on unpleasant scenarios. They matter even more after launch because real users bring new wording, new failures, and new documents. A good eval set lives with the product.
The practical benefit is simple. The team stops arguing whether something “feels better” and starts seeing which scenarios passed, which failed, where quality drifted, and where a cheaper model can replace an expensive one. Less mystical, more useful.
What an eval actually is
An eval is a repeatable quality check for an AI system.
Sometimes it is a simple assertion: the output must be valid JSON, contain a source link, stay under 800 characters, or call the right tool. Sometimes it is a human review rubric. Sometimes it is an LLM judge that reads the input, retrieved context, and answer, then gives a score.
The important part is not the tool. The important part is that the same scenario can be run again after a prompt change, model change, retrieval change, or product release.
That makes evals different from a demo. A demo shows that the agent can work once. An eval shows whether it still works when the boring engineering reality begins: new documents, new user wording, cheaper models, changed prompts, broken integrations, and edge cases no one proudly puts in a slide deck.
| Demo | Eval | |
|---|---|---|
| What it shows | the agent worked once | the agent works across the whole scenario set |
| How it is judged | "looks good" | against criteria and a threshold: by code, a person, or a judge model |
| When it runs | before a meeting | after every prompt, model, retrieval, or tool change |
| What the team gets | confidence in a presentation | a decision on whether the new version can ship |
Why prompt testing by vibe fails
Most AI projects start with a familiar loop:
- Someone edits the prompt.
- They try five examples in a chat window.
- Two answers look better.
- One answer looks weird.
- The team ships because the meeting is ending.
This is understandable. It is also how regressions sneak in.
AI systems are awkward because a change can improve the visible examples and break a hidden slice of behavior. A stricter prompt may reduce hallucinations but increase unnecessary refusals. A cheaper model may handle simple FAQ answers well but fail on messy multi-step cases. A new retriever may improve semantic matches and make exact IDs worse.
Without evals, those trade-offs stay invisible. The argument becomes taste: “this answer feels better”, “the old one sounded warmer”, “the new model seems smarter”. Evals do not remove judgment, but they move the discussion closer to evidence.
Start with error analysis, not a giant test suite
The best first eval set is usually small and irritating.
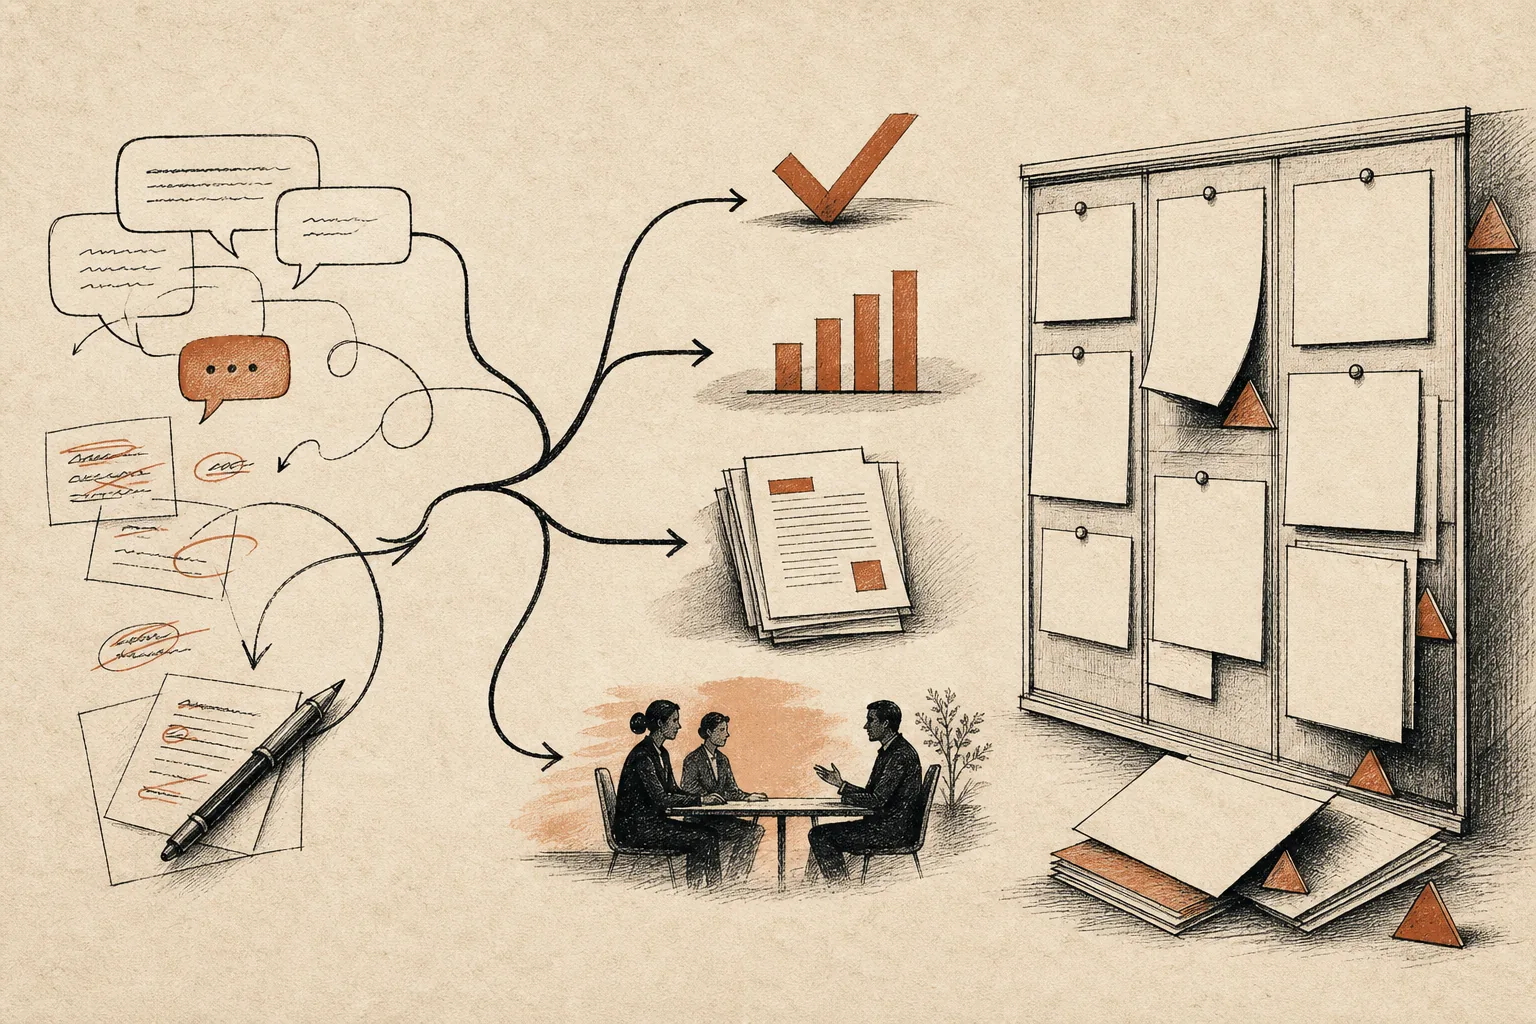
Take 20-50 real or realistic examples. Do not cherry-pick only happy paths. Include the support ticket where the agent invented a policy, the sales chat where it promised a discount, the HR question where access rules mattered, and the document search where the right answer was hidden in a table.
For each example, write down:
- the user input;
- the documents, CRM records, or tool results the system should use;
- the answer or behavior you expect;
- what would make the answer unsafe or useless;
- how severe the mistake is.
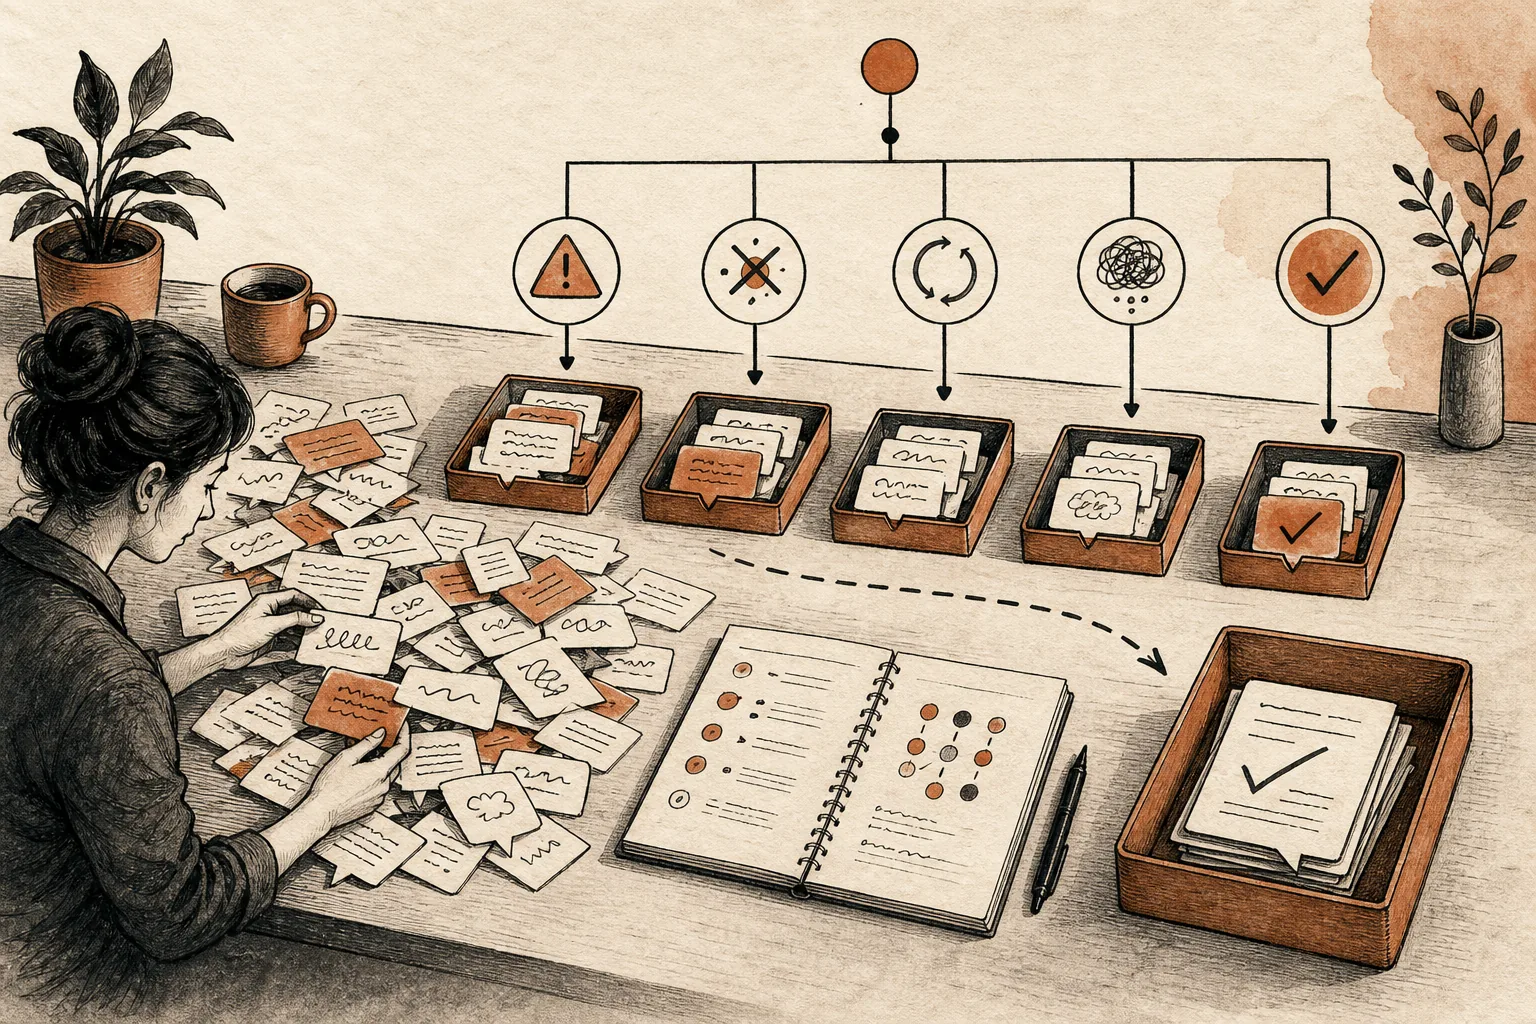
Then tag the failures. The labels can be plain: wrong source, unsupported fact, missed escalation, bad tool call, too verbose, access violation, wrong language, format broken.
After a short review, patterns appear. Maybe the agent is fine on FAQ but bad on pricing exceptions. Maybe RAG retrieves the right document but the model ignores the table. Maybe sales follow-ups are good until the client asks for a promise the company cannot make.
Build evals around those patterns first. Generic metrics are useful later. The first job is to catch the mistakes that would actually hurt the business.
Three layers of evals
Production evals usually combine three layers.
Deterministic checks catch things code can know. Did the answer fit the schema? Did the agent call create_crm_task only after extracting a customer ID? Did it include a source? Did it refuse a forbidden request? Did it stay within a token or character budget?
These checks are cheap, fast, and boring in the best way. Use them wherever possible.
Human review is still needed for judgment. A person can say whether a summary missed the real decision, whether a sales answer sounds too pushy, or whether an internal policy answer would confuse an employee. Human review is also the calibration set for LLM judges.
LLM-as-judge helps scale semantic review. A judge model can score faithfulness, completeness, answer relevance, tone, or instruction following. It is practical, but it is not magic. The judge needs a clear rubric, thresholds, examples, and periodic comparison with human labels.
Frameworks like DeepEval are useful because they give this workflow a familiar shape: datasets, test cases, metrics, thresholds, repeated runs. Treat the framework as a harness, not as the source of truth. The business task decides the metric.
DeepEval, Ragas, OpenAI Evals, promptfoo, Braintrust, LangSmith, and Phoenix all solve parts of the same problem. Some are better as local test runners. Some are stronger at tracing, datasets, experiments, or production monitoring. Do not start by picking the logo. Start with the failure you need to catch.
| Tool | Good for |
|---|---|
| DeepEval | pytest-style tests with LLM metrics, runs in CI |
| Ragas | RAG metrics: faithfulness, context precision and recall |
| promptfoo | config-driven prompt and model comparisons, red teaming |
| OpenAI Evals | running OpenAI models against your own datasets |
| Langfuse | tracing, datasets, and LLM-as-judge in one open-source tool |
| LangSmith | tracing, datasets, and experiments, especially alongside LangChain |
| Braintrust | experiments and version comparisons on datasets |
| Phoenix | open-source tracing and evals from Arize |
What to test in RAG
RAG deserves its own evals because “the answer is wrong” can mean several different things.
If retrieval failed, the model may be innocent. It answered from the wrong context because the system gave it the wrong context. If retrieval found the right passage and the model still invented a fact, then the prompt, model, context format, or refusal rule is the suspect.
For a deeper look at retrieval architecture, see How RAG works and why vector embeddings are not enough. The short version for evals:
- Retrieval recall: did the system find the source that contains the answer?
- Retrieval precision: did it bring too much irrelevant material?
- Source coverage: is there enough context to answer, or should the agent say it does not know?
- Faithfulness: did the final answer stay inside the retrieved evidence?
- Citation quality: do the links or excerpts actually support the claims?
- Access control: did the answer use only documents the user is allowed to see?
This matters a lot for an internal ChatGPT for a company. Employees will ask messy questions: “what do we do with this client?”, “is this expense allowed?”, “where is the latest template?” Confidence is not enough. The assistant has to find the right source, respect roles, and admit when the knowledge base is missing the answer.
What to test in agents and tool use
Agents add another failure surface: actions.
A chatbot can be wrong in text. An agent can be wrong in the CRM, calendar, ticket system, database, or email draft. That changes the eval set.
For an agent, test:
- whether it chooses the right tool;
- whether it passes the right arguments;
- whether it checks tool results before continuing;
- whether it stops when required data is missing;
- whether it asks for confirmation before risky actions;
- whether it leaves a useful log for a human.
For example, in AI for sales teams, an eval should check more than whether the follow-up email reads well. It should verify that the agent captured the next step, avoided forbidden promises, updated the right CRM deal, and escalated pricing exceptions to a manager.
Good evals make autonomy negotiable. You can allow an AI agent to draft, then later allow it to create tasks, then later allow it to send low-risk messages. Each step gets its own evidence.
What evals look like in a real project
In the Magnum HR agent, the eval set comes from real candidate conversations: 100 questions in Russian and Kazakh with reference answers. A separate judge model scores tone, correctness of terms, and naturalness. The suite also checks whether the agent walked the candidate to a trial-shift booking and called the right tools, such as the geocoder and store search. The judge was checked against human labels before anyone trusted it. Passed tests are held at 100%: a score drop blocks the release.
In the Magnum staff knowledge base, evals are split into two layers. The base is a benchmark of 100 real employee questions in two languages, with every reference answer pinned to a specific document. Retrieval is checked first: did the right document land in the results, and how high. Then the answer: does it match the reference, and does it name the right source. A new prompt, model, or document markup passes the benchmark before it reaches employees.
If a product serves more than one language, the set needs all of them, including mixed-language messages. A demo in one language says little about how the agent handles the other.
A practical eval set for the first month
You do not need a research lab to start.
For a first production AI project, I like a simple set:
- 30-50 seed examples from real work;
- 10-20 nasty edge cases written by the team;
- a handful of “must refuse” examples;
- a few long-context examples;
- a few multilingual examples if the product is bilingual;
- a holdout set that is not used while tuning prompts.
Each example should have an owner. Someone in the business must be able to say: this is good enough, this is dangerous, this is merely ugly.
Run the visible set during development. Keep the holdout set for release checks, so the team does not accidentally overfit the prompt to the examples everyone has memorized.
When production produces a serious miss, add it to the suite. That is how evals become useful instead of ceremonial. Every painful bug buys a future regression test.
How evals affect cost
Evals are part of quality work, but they are also part of cost control.
The expensive model may not be needed everywhere. Once the team can run the same scenarios across models, it can compare quality, latency, and price. Maybe common FAQ answers pass on a cheaper model. Maybe document-heavy legal questions need the stronger one. Maybe agent planning needs the expensive model, while final formatting does not.
That is why evals belong in the budget discussion. In How much does AI implementation cost in Kazakhstan?, the same point shows up from another angle: production AI cost is not just the model call. It is the work needed to make the system measurable, maintainable, and safe enough to run around real users.
Without evals, model switching is a guess. With evals, it becomes an engineering decision.
Where evals fit in the workflow
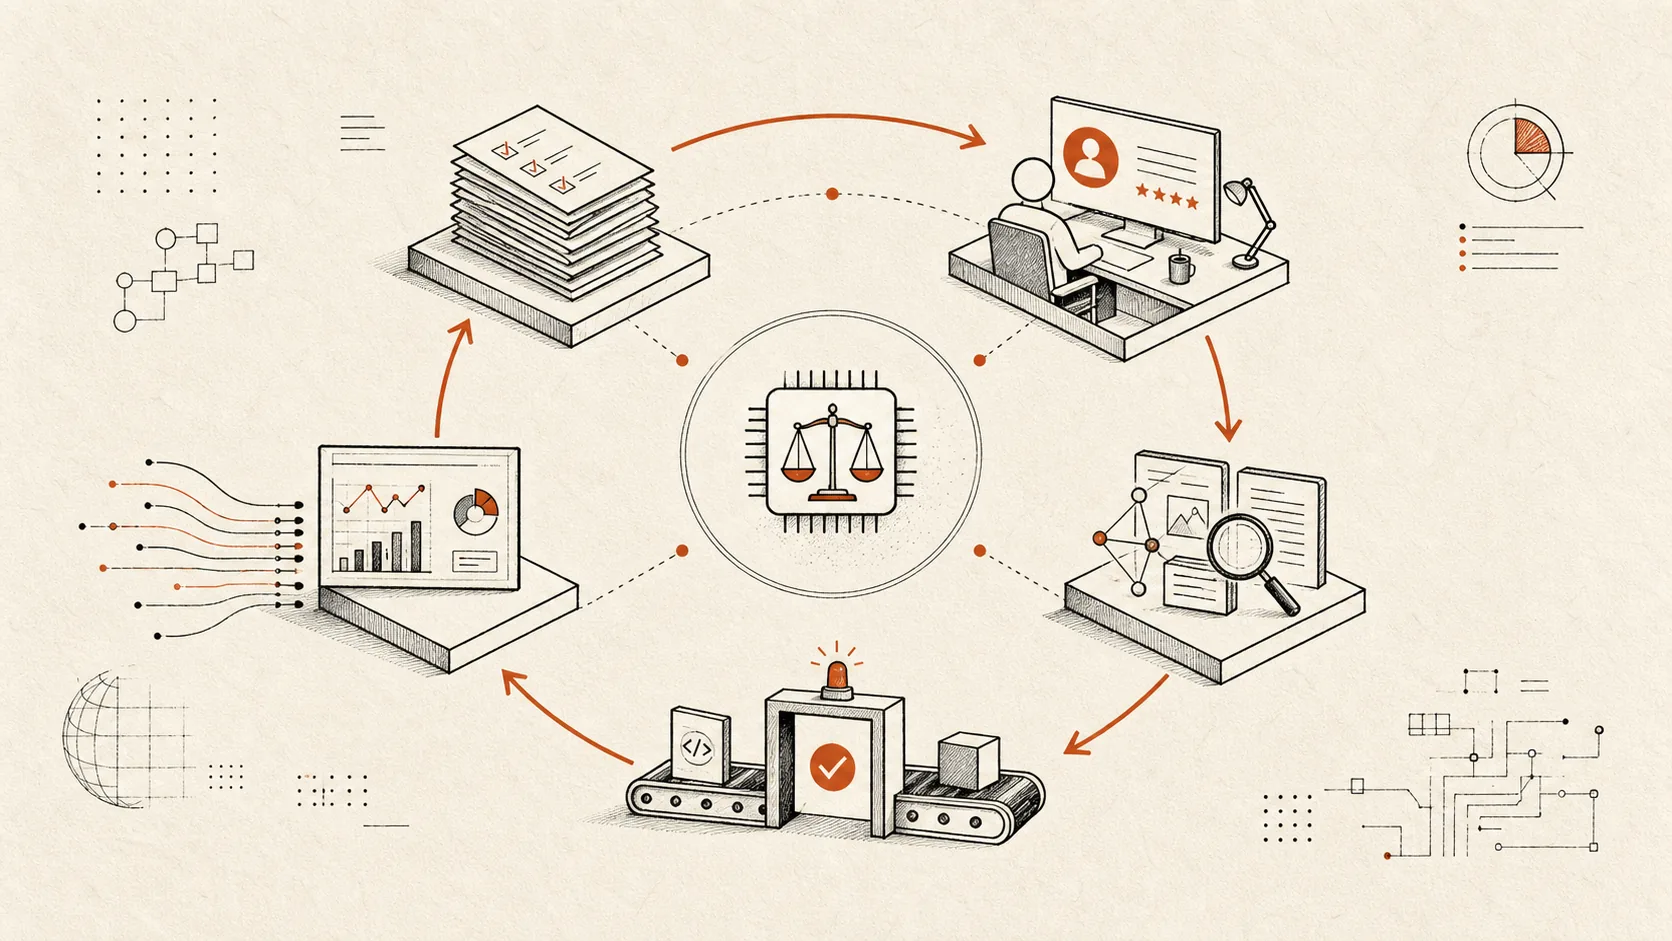
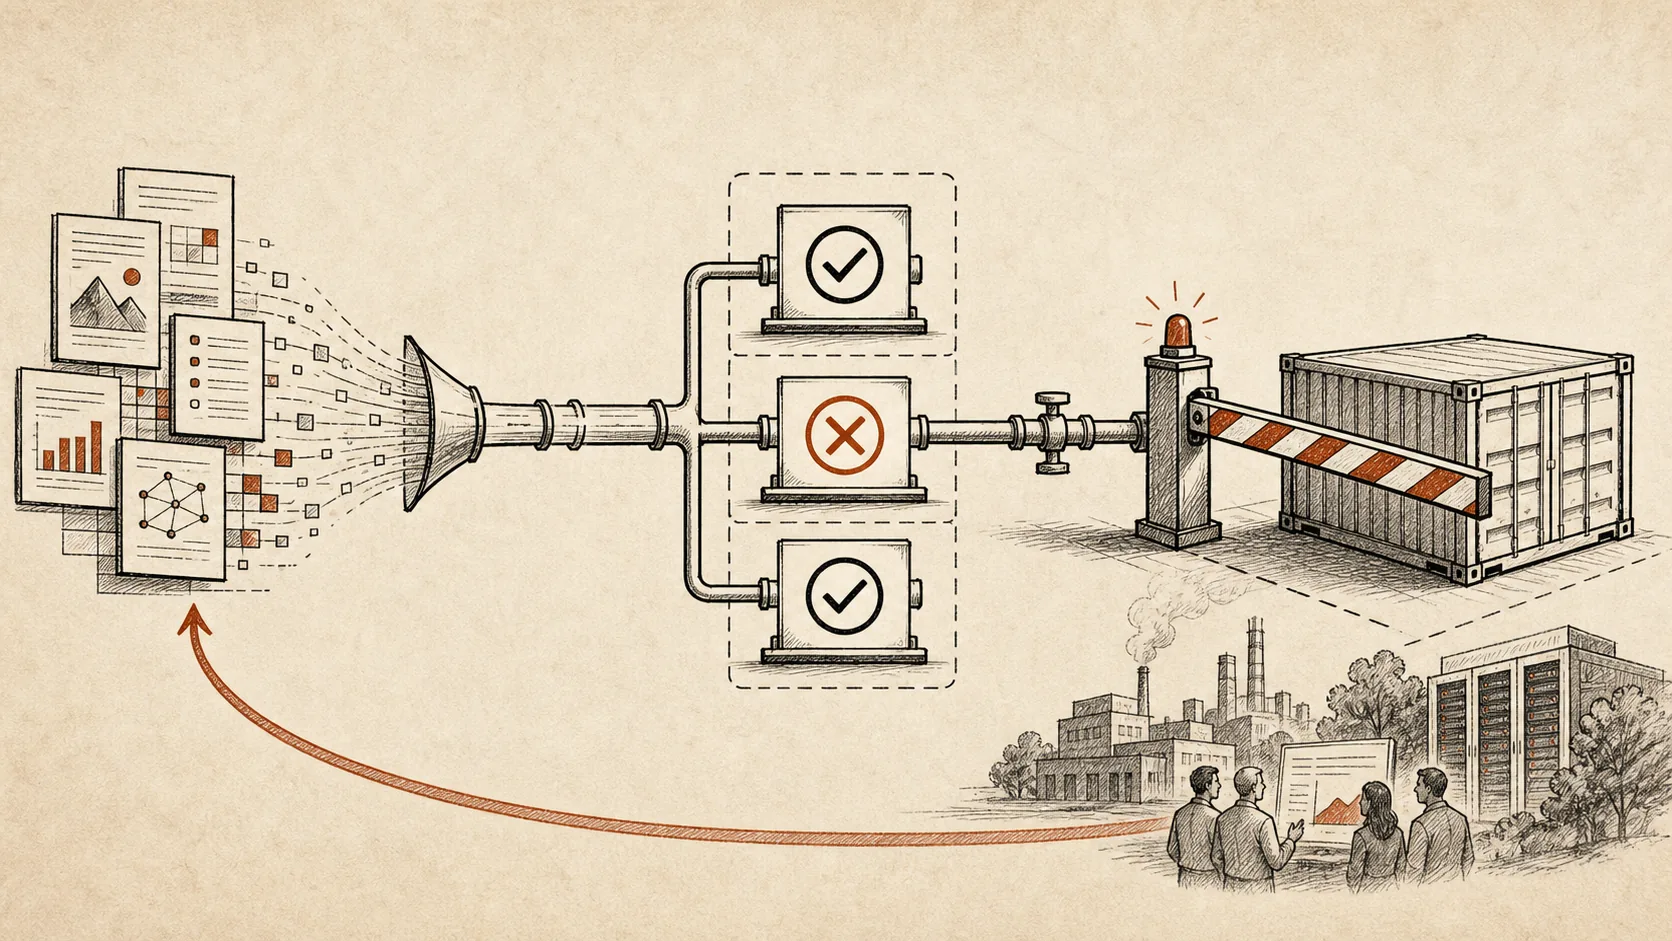
A healthy loop looks like this:
- Collect examples from real usage or realistic scenarios.
- Review them manually and name the failure modes.
- Convert the most important failures into deterministic checks, human rubrics, or LLM-judge metrics.
- Run the suite before prompt, model, retrieval, or tool changes ship.
- Keep a holdout set for release confidence.
- Add production bugs back into the suite.
CI can run the fast checks on every change. Slower LLM-judge runs can happen before release or on a schedule. Human review can focus on new failure types instead of rereading the same obvious cases forever.
The point is not to make AI perfectly predictable. It will not be. The point is to make change safer. You want to know when quality moved, where it moved, and whether the movement matters.
FAQ
What are AI evals in simple terms?
AI evals are an exam for an AI system. You collect real questions and tasks in advance, define what a correct answer or action looks like, and rerun the system against that set after every change. The result is a count of which scenarios passed and which broke.
How is an eval different from a normal software test?
A normal test checks an exact result: the function returned 42 or it did not. A model words its answer differently every time, so an eval checks behavior: did the agent find the right source, avoid invented facts, and hand a hard case to a person. Some checks are code; others need a human or a judge model.
How many examples does a first eval set need?
Thirty to fifty real examples plus ten to twenty nasty edge cases from the team are enough to start. Production sets usually grow to 100-200 requests with reference answers. Keep part of the set aside and never use it while tuning the prompt: that holdout is what you sign off a release on.
Which tool should we use for evals?
Pick the tool after you know which failures you need to catch. DeepEval suits CI tests, Ragas covers RAG metrics, promptfoo compares prompts and models, and Langfuse or LangSmith trace and score live conversations. A small set can live in a spreadsheet and a script.
Can you trust LLM-as-judge scores?
Only after calibration. A judge model makes mistakes too. Grade a few dozen answers by hand and compare them with the judge's scores. If they disagree often, tighten the rubric and add examples. The judge should also be a different model from the one that produced the answer.
Does a small project or pilot need evals?
Yes, at a small scale. Even a pilot needs a few dozen real questions and a success threshold agreed in advance. Without them, the pilot ends in an argument about impressions, and nobody can say whether to launch.